01 // BUSINESS PROBLEM & STRATEGY
THE PROBLEM THAT NEEDED SOLVING
Procurement documents arrive in inconsistent formats and contain structure that generic text extraction can easily destroy: sections, clauses, tables, page boundaries, vendor context, and archive structure.
WHAT WAS ACTUALLY IMPLEMENTED
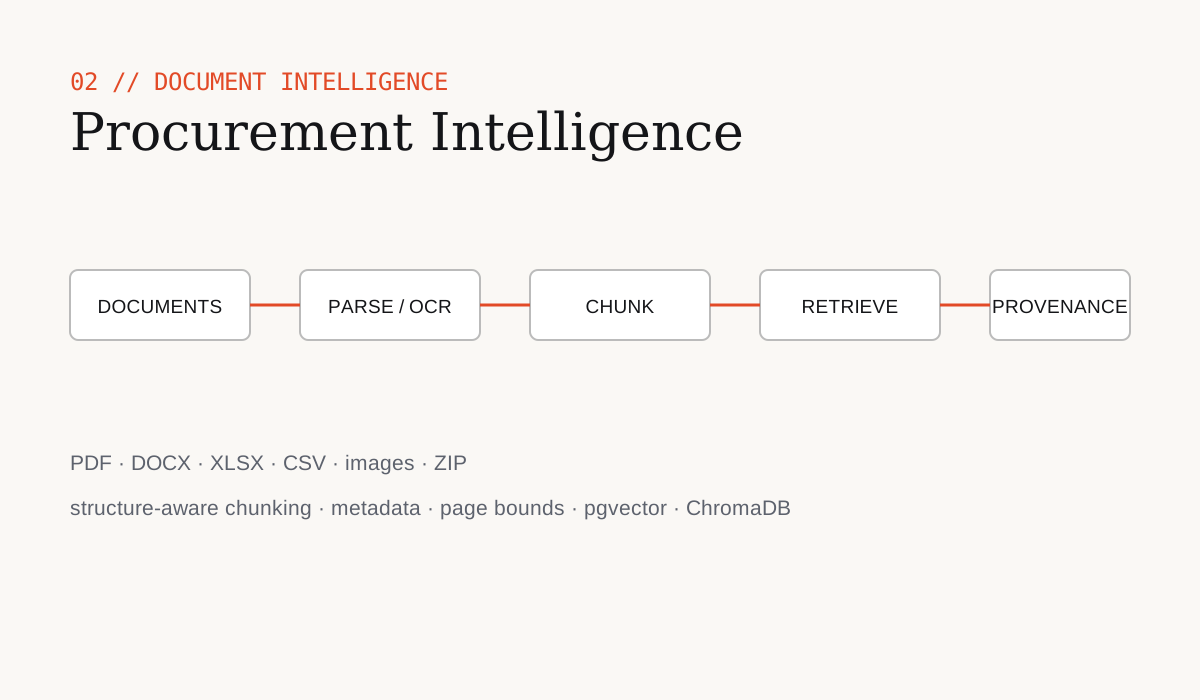
Built a format-aware ingestion pipeline that validates inputs, routes supported formats to dedicated parsers, normalizes content into a canonical document model, enriches provenance metadata, and applies structure-aware chunking before vector storage.
02 // TECHNICAL IMPLEMENTATION & ARCHITECTURE
The ingestion layer includes safe ZIP inspection with a Zip-Slip path traversal shield, multi-encoding CSV detection, table-preserving chunking, and provenance carried from source file through normalized blocks and chunks.